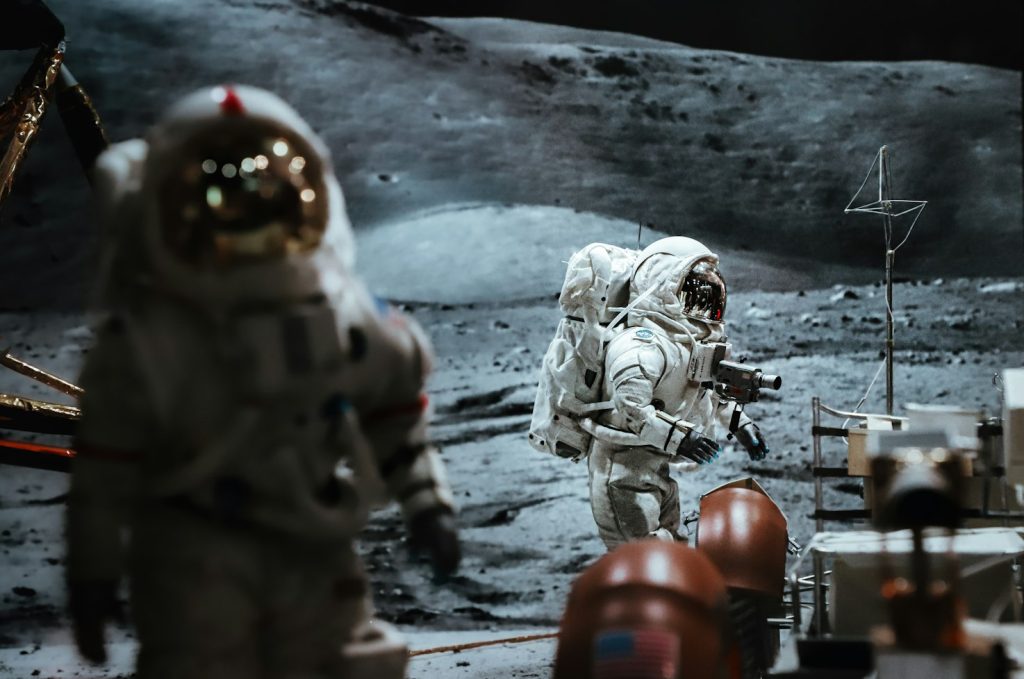
A signal from Mars needs up to 24 minutes to reach Earth. From Voyager 1, closer to a full day. It arrives weak, packed into CCSDS frames, and only during a booked downlink window that may not come back for another 12 hours. Many legacy on-premise stores can’t decode and index one pass before the next one begins. Packets queue up, analysts wait, and the flight team steers the spacecraft using yesterday’s picture of its health.
Deep Space Downlink Bottlenecks: Why Legacy Telemetry Pipelines Fall Behind
Science instruments have grown much faster than the systems that receive their output. A modern imaging spectrometer or radar sounder can fill a Ka-band pass with gigabytes of data. JWST, for example, sends its science data down through the DSN in Ka-band. Most ground pipelines feeding mission control, however, were designed when a “big” pass meant a few hundred megabytes of housekeeping data.
The receiving antenna is rarely the problem. The trouble starts afterward.
At many stations, the processing flow still looks like it did in 2005. Frames are written to files at the complex. Those files are shipped to the MOC after the pass ends. Decoding runs on a dedicated server, and indexing finishes sometime overnight. If the next pass starts before the first one is cleared, both passes slow down.
These are the most common choke points:
- Batch-first design. Nothing can be queried until the entire pass has landed as a file.
- Serial decoding. Reed-Solomon, turbo or LDPC decoding runs on a single machine, one virtual channel at a time.
- Siloed archives. Goldstone, Madrid and Canberra data can end up in separate stores with separate schemas.
- Rigid packet definitions. A new instrument APID means hand-editing mapping tables before anyone can read the values.
- Painful gap repair. Missing frames are found hours later. By then, re-requesting them through CFDP or SLE replay competes with the next science pass.
Does any of this sound familiar? It should. The pattern shows up across agency and commercial missions alike. To merge telemetry streams from many ground stations, keep query latency low and run analysis on a reliable cloud architecture, space operators increasingly work with a certified Snowflake partner to build a secure, high-performance data management system instead of adding yet another archive tier.
Real-Time Signal Parsing: From Raw RF Streams and CCSDS Frames to a Structured Data Lake
Where the fragments actually disappear
Low SNR is a given in deep space. A probe near Jupiter transmits with roughly the power of a household light bulb, and only a tiny fraction of that energy reaches a 70-meter dish. The DSN compensates by arraying several 34-meter antennas, and modern turbo and LDPC codes perform close to the Shannon limit. Even so, the margin for a bad pass is thin.
Most data losses are not caused by the physics, though. They happen in software. A frame sync slips after a short signal dropout. A buffer overflows while the decoder catches up. A virtual channel counter wraps around, and a simple script reads the wrap as a duplicate. Small faults like these are what turn a clean pass into one with gaps.
A parsing chain that keeps everything
A modern pipeline treats the downlink as a continuous stream rather than a file to process later. The working steps look like this:
- SDR front end. Software-defined receivers such as Kratos quantumRadio or a GNU Radio-based chain digitize the RF signal and can stream it as IQ samples.
- Frame synchronization. The receiver locks onto the CCSDS Attached Sync Marker (0x1ACFFC1D) and keeps the soft-decision bits, so a frame that fails decoding can be decoded again later with better parameters.
- Decoding and virtual channel demultiplexing. These run in parallel, one worker per virtual channel, so a busy science channel doesn’t hold up housekeeping data.
- Space Packet reassembly. Packets are rebuilt by APID. Any gap in the sequence count is flagged immediately, not discovered in a morning report.
- Dual timestamping. Each packet carries both its Earth Received Time and the spacecraft clock value (CUC), with the time correlation recorded alongside it.
- Streaming ingest. Packets flow through Kafka or Snowpipe Streaming into Iceberg or Delta tables that analysts can query within seconds.
The key point is simple: the raw data is never thrown away. When the flight dynamics team updates the time correlation model three weeks later, the history can be reprocessed from the original bits instead of being patched by hand.
Centralizing Multi-Network Ground Data: DSN, ESTRACK and Commercial Dishes as One Source of Truth
Cross-support between agencies is not new. ESA’s 35-meter antennas at New Norcia, Cebreros and Malargüe regularly track NASA spacecraft, and the DSN returns the favor. The CCSDS Space Link Extension (SLE) services, mainly RAF and RCF, make the frames themselves interoperable.
Interoperable frames do not automatically produce a unified dataset, however.
The commercial layer adds further variety. AWS Ground Station delivers data straight into a customer’s VPC. KSAT runs one of the densest polar networks in operation. Goonhilly in Cornwall has supported lunar missions with deep-space-class antennas. Microsoft’s Azure Orbital initiative relied on partner networks like KSAT and Viasat before the company scaled back its own ground station service. Each of these providers delivers data in a slightly different format, with different timestamps and metadata.
Consider a pass handed over from Canberra to Madrid with a 20-minute overlap. The same frames arrive twice, from two continents, with slightly different reception times. Which copy is correct? Ideally, the system keeps the best copy and records where both came from.
A workable unification layer usually follows these rules:
- A deterministic frame key: spacecraft ID + virtual channel ID + VC frame count + coarse ERT. With that key, duplicates collapse on their own.
- Quality-ranked deduplication: when two copies conflict, the frame with the cleaner decoder status and better Eb/N0 wins.
- One time standard everywhere: UTC with leap seconds handled explicitly, never local station time.
- A shared packet dictionary maintained as versioned data rather than spreadsheets passed around by email.
- Provenance columns on every row recording the station, antenna, receiver and pass ID.
The platform choice depends heavily on existing infrastructure. Snowflake Data Cloud suits teams that want separated compute and strong governance. Databricks appeals to groups that do heavy ML work on Delta Lake. Google Cloud BigQuery is common among Earth observation operators. Palantir Foundry has gained traction in defense programs where the operational ontology matters as much as the queries. Planet Labs, running hundreds of spacecraft, is a useful example at fleet scale: at that volume, manual ground processing stops being an option.
High-Parallel Analytics for the MOC: Trajectories, Thermal Swings and Battery Health
Orbit determination needs fresh tracking data
Flight dynamics depends on radiometric data: two-way Doppler, ranging and delta-DOR. These measurements arrive as CCSDS Tracking Data Messages and feed orbit determination tools such as NASA’s MONTE or the open-source GMAT. If tracking data reaches the navigation team four hours late, the next trajectory correction maneuver is planned on an older solution. That matters ahead of a flyby.
With parallel ingestion, the latest tracking arc can be in the OD run within minutes of the pass ending.
Thermal and power are time-series problems
Temperature swings during a slew. Battery depth of discharge through an eclipse. Heater duty cycles as the spacecraft moves away from the Sun. All of these are time-series questions, and they share the same workload profile: windowed aggregations over billions of rows, joined on timestamps that never line up exactly.
This is where the database engine makes a real difference. Time-series stores like InfluxDB or TimescaleDB handle narrow, fast-moving channels well. Cloud warehouses now offer ASOF joins, which match a battery voltage sample to the nearest heater state without resampling everything to a common grid. Typical analyst questions look like this:
- Which three thermal zones drifted beyond 2°C of their predicted value during the last four passes?
- How did state of charge recover after the last solar conjunction blackout compared with the one before?
- Is the reaction wheel current trending upward, or is that just noise in the last week of data?
Then there is concurrency. What happens when 40 engineers query the same 3 TB table during an anomaly review? On a shared on-premise cluster, everyone slows down. With isolated compute warehouses, the anomaly team gets its own resources and routine science queries are unaffected.
The Metrics That Matter: Engineering and Operational Numbers
Benchmarks are only useful when they come with specific numbers. The figures below are the kind of targets that well-designed modernization programs report after moving from batch processing to streaming:
- Telemetry readiness: from about 4 hours to about 12 seconds. Analysts can query decoded, indexed CCSDS packets about 12 seconds after a frame leaves the receiver, instead of waiting for an overnight batch job.
- Packet loss below 0.001%. This comes from soft-bit retention, automatic gap detection, and multi-station deduplication that recovers frames a single site missed.
- Up to $15,000 saved per hour of contact time. The savings come from avoiding repeated passes, fewer replay requests on busy apertures, and fewer operator hours spent reconciling archives. Antenna time on a 70-meter dish is scarce, and every wasted hour has a cost.
- Reprocessing measured in minutes. Re-decoding a month of history after a calibration update becomes a parallel job instead of a week of manual work.
A caution is in order. None of this works without disciplined operations. A streaming pipeline built on an outdated packet dictionary will simply deliver wrong values faster. Configuration control, test passes with simulated frames, and clear ownership of each APID matter as much as the cloud platform behind them.
The antennas are already capable of catching weak signals across billions of kilometers. In most programs, the larger opportunity now lies in the ground pipeline: how quickly data moves from the dish to the people who need it.
Author
Written by
Recent Posts
Streamlining Ground Station Data Pipelines for Deep Space Missions
The Coordination Problem That Kills Growing Marketing Teams
Why Personalized Skincare Is Replacing One-Size-Fits-All Beauty Products
The Return of the Transatlantic Crossing
How Molecular Spectroscopy Uncovers Structural Details In Molecules
Categories
- Art
- Articles
- Business of Luxury
- Celebrities
- Culture
- Entertainment
- Events
- Faces of Summer 2026
- Fashion
- Fashion & Style
- Featured
- Finance
- Food, Spirits, Wine
- Hamptons
- Hamptons Celebrities
- Health
- Health & Beauty
- Lifestyle
- Luxury Lifestyle
- Press
- Profiles
- Real Estate
- Technology
- The Chronicles
- Travel
- Uncategorized
- Weddings